ASUS Ascent GX10

ASUSMini PC reference

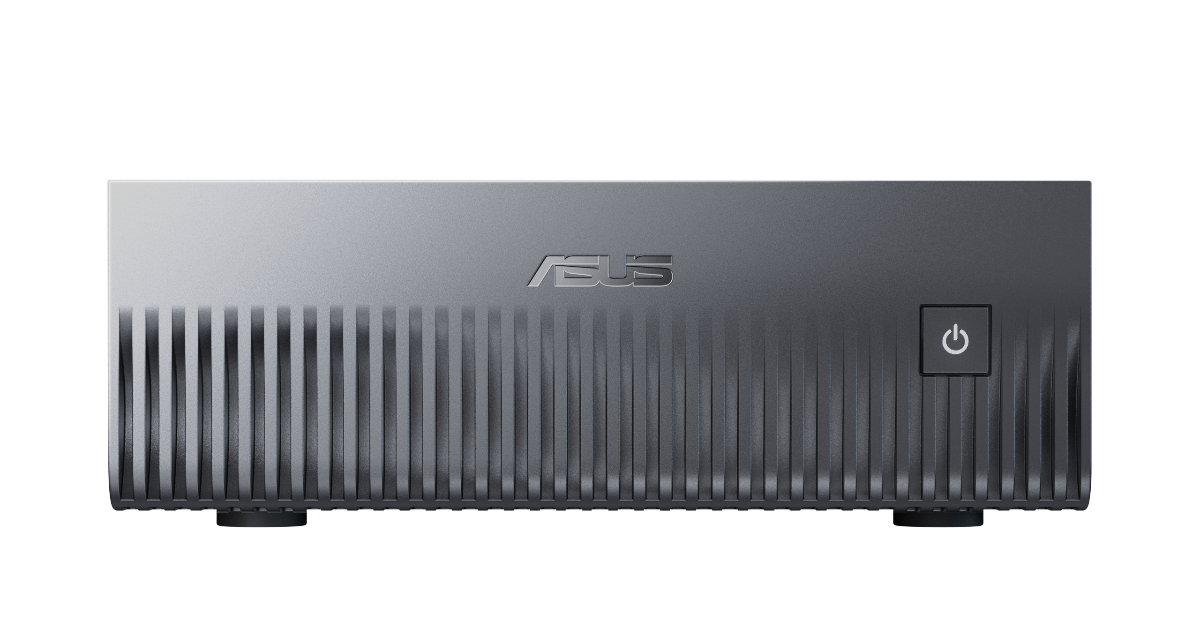
ASUS Ascent GX10

ASUS Ascent GX10 is a Linux-based AI workstation built around NVIDIA GB10 and 128 GB of unified memory. It is aimed at local model development and inference, with 10GbE and ConnectX-7 connectivity. Check ARM Linux and application support before treating it as a general-purpose Windows desktop; theoretical AI compute is not a measured tokens-per-second result.

Processor
NVIDIA GB10
Graphics
NVIDIA Blackwell
Memory
128 GB
Storage
1 TB
Configuration being compared128 GB RAM · 1 TB SSDNew
US stores · USD

Prices across stores

MiniPC.guru compares retailer listings. Purchases are completed on the retailer’s website.

View price history
RetailerAvailabilityListed priceLast checkedRetailer website
In stock$5,999Lowest checkedView at Newegg
In stock$5,999.95View at MITXPC
Out of stock$6,059.99View at CDW
Out of stock$6,232View at eSaitech
Out of stock$5,999View at LTT Partners
Out of stock$5,891.54View at NEBuMAX
Out of stock$6,193.59View at PCNation

Availability reflects the latest store check. Shipping, tax, coupons and checkout totals are not included; confirm them at the store.

Specifications

Processor, graphics and installed memory/storage describe the selected configuration. Expansion limits and connectivity describe the model; optional hardware is identified separately. References are collected in About this data below.

Processor
NVIDIA GB10
Graphics
NVIDIA Blackwell
Memory
128 GB
Storage
1 TB
Ports & displays
3 × USB-C 20Gbps with DisplayPort 2.1 Alt Mode, 1 × USB-C 20Gbps with power input, HDMI 2.1 and NVIDIA ConnectX-7 network interface.
Ethernet, Wi-Fi & Bluetooth
1 × 10GbE RJ45 plus NVIDIA ConnectX-7 SmartNIC; AW-EM637 Wi-Fi 7 (2×2) and Bluetooth 5.4.
RAM & storage upgrades
128 GB LPDDR5x unified memory. One M.2 SSD slot; ASUS documents 1 TB PCIe 4.0 and 4 TB PCIe 5.0 versions, with up to 4 TB storage. Do not treat system memory as a replaceable SO-DIMM kit.
Power supply & power limits
ASUS launch specifications list an adapter output up to 240 W (USB-C PD 3.1 EPR) and a device input maximum of 180 W. These are electrical ratings, not measured workload consumption.
Dimensions & weight
150 × 150 × 51 mm (W × D × H); ASUS-listed weight 1.48 kg.

Our test

MiniPC.guru test

We tested our own ASUS Ascent GX10 (128GB · 1TB). The test date above is US Eastern time; the raw files use UTC. Results come first, then the setup, what we did not measure and the raw files. Every result in this section comes from those files; hardware details come from ASUS and NVIDIA, and model sizes from the model card.

One user, short question

A 33-token question, three runs: 77.94 · 77.95 · 77.95 tokens per second, generating 301, 305, 301 tokens. Median first word 0.07 s (0.16 s on the first, cold run).

Long documents

Excerpts of Moby-Dick (public domain) of 3 lengths, each with one note hidden at 75% of the text that holds a secret number. The model had to answer with the number. The first word includes reading the whole document.

Input tokensFirst word (s)Output (tokens/s)Hidden number found
8,6201.7473.97Yes
30,8326.4365.55Yes
94,72226.5648.51Yes

Many users at once

Requests sent at the same moment, each one asking a different question and generating exactly 256 tokens.

UsersTotal tokens/sPer user, medianPer user, slowestFirst word, median (s)
176.377.3177.310.06
4187.947.9947.730.14
8276.135.2535.240.18
16391.325.0124.940.27
32530.417.0216.860.45

Image and video generation

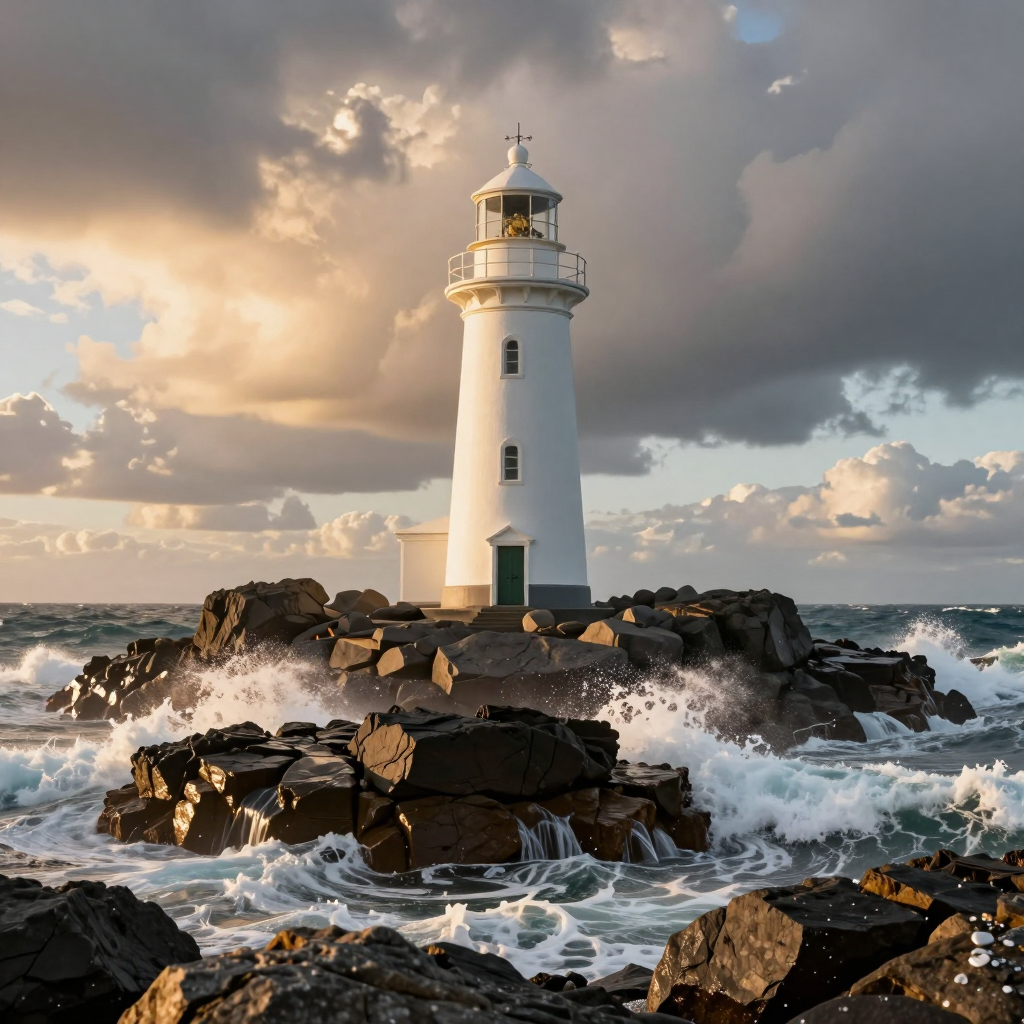
Z-Image Turbo, 1024 × 1024, 8 steps: one warm image in 7.5 s (16.1 s for the first one, which includes loading the model). Wan 2.2 TI2V 5B, a 121-frame clip at 24 fps (1280 × 704, 20 steps): 5 min 26 s. Both are open models under the Apache 2.0 license.

Image generated on this machine with Z-Image Turbo: a lighthouse on a rocky coast
Generated on this machine with Z-Image Turbo (1024 × 1024, 8 steps), shown as produced.
Generated on this machine with Wan 2.2 TI2V 5B (121 frames at 24 fps, 1280 × 704, 20 steps).

Power and temperature

GPU power as reported by nvidia-smi every 0.5 s, not measured at the wall: 10.8 W idle with the language model loaded and 3.3 W with nothing loaded; up to 94 W reading the longest document, 40 W serving 32 users, 94 W generating an image and 98 W generating video (89 W on average). Highest GPU temperature: 75 °C on text and 86 °C on video.

Test setup

Operating system
DGX OS 7.6.0 (Ubuntu 24.04.5 LTS), kernel 7.0.0-1019-nvidia
Driver
NVIDIA 580.178.04 · CUDA 13.0
Processor
NVIDIA GB10: 10 × Cortex-X925 + 10 × Cortex-A725 (20 Arm cores)
Memory
128 GB LPDDR5X unified memory; 121.6 GiB visible to Linux
Storage
1 TB NVMe SSD (as shipped)
Language model
nvidia/Qwen3.6-35B-A3B-NVFP4: 35B parameters, about 3B active per token, 4-bit NVFP4 weights (sizes from the model card)
Runtime
vLLM 0.28.0 OpenAI-compatible server, streaming; context window 131,072 tokens; 32 GiB KV cache; up to 64 concurrent requests; no speculative decoding
Settings
Thinking disabled by a custom chat template; temperature 0.3; answers capped at 320 tokens (short question) and 200 tokens (documents); the many-users test forces exactly 256 tokens per request (ignore_eos)
Client
Python client on the same machine; every streamed chunk timed with the local clock
Image and video
ComfyUI with the official Z-Image Turbo (bf16) and Wan 2.2 TI2V 5B (fp16) templates; language model stopped during these tests

What we did not measure

Wall power, noise, network throughput and storage speed. This is one unit on one day; other units, firmware or software versions can give different results.

Raw data

The raw files behind every result. Before publishing we replaced the machine name and internal paths, and took the image and video out of bench-gen.json: their size and SHA-256 stay in it, and the files are listed here.

  • run.json17 KB · SHA-256 ec112d2c634c16cb7e2a02218307ba32e55021833450d217db397547d9e9a3d7
  • bench-llm.json125 KB · SHA-256 49391d800b9bf32c7d27c31965a109883d32cbd1e8f7386762bc04952442d523
  • bench-gen.json27 KB · SHA-256 dc7ee2dcb26ac9bbb071163e0243f9e7cca05595bdf82c4794f7a256ecb9a9a1
  • z-image-turbo.png1.3 MB · SHA-256 b4c5db1787983ecf1b565d94d8f908f5ae2e1ce1dd74c951c51591f6c975d536
  • wan22-ti2v-5b.mp44.5 MB · SHA-256 60c981d74522a433ac6f552eb14a180795cd9cd2f4eafda885940c947070db5e

Video

Plays on YouTube. Nothing is loaded from YouTube until you press play. YouTube

What owners say

We tested our own unit with NVIDIA's own 4-bit build of a 35-billion-parameter mixture-of-experts model. One user got 78 tokens per second, with the first word in under a tenth of a second. With 32 people asking at once it delivered 530 tokens per second in total, about 17 each, and a 95,000-token document took 27 seconds to read before it answered at 48 tokens per second and found a note we had hidden inside. Owners report the same strength at larger scale: one pushed a real prompt of 261,537 tokens through it and was still getting 17.7 tokens per second. Another compared it against a MacBook Pro with a single model answering a single question, reported the laptop at roughly twice the speed, and was told that single-stream generation is governed by memory bandwidth. Two things owners had to work out for themselves: idle draw depends on the firmware, 42 to 47 W in an early review against about 25 W for owners on mid-2026 firmware after a power fix for the network controller, and the widely quoted 140 W is the whole chip's rating, as NVIDIA confirmed in its own forum.

For whom
Very long contexts, large models kept in memory and several people served at once, for someone comfortable on ARM64 Linux and careful about which model build they run.
Not for
Single-user speed on small models, where a laptop with faster memory can win, and anyone who needs a desktop that simply works today.

Our own summary of 6 published sources and our test of this Mini PC on Sep 25, 2026, reviewed Sep 25, 2026. Our test, with its raw data, is in the “Our test” section of this page; the other sources are listed under About this data.

Performance

5 sourced resultstok/s

Same model, quantization, context length, prompt, output length, runtime version and batch size. Record time to first token separately.

Measured by MiniPC.guru on our own unit. The “Our test” section of this page publishes the raw data, software versions and exact settings.

77.95 tok/sMiniPC.guru test
Our test of the ASUS Ascent GX10 ↑

By MiniPC.guru · MiniPC.guru

Source published
Sep 25, 2026
Test performed
Sep 25, 2026
Added to MiniPC.guru
Sep 25, 2026
Source reviewed
Sep 25, 2026
Tested hardware
NVIDIA GB10, 20 Arm cores (10 × Cortex-X925 + 10 × Cortex-A725) · NVIDIA GB10 integrated Blackwell GPU · 128 GB LPDDR5X unified memory, 121.6 GiB visible to Linux · not applicable: the model is fully resident in memory
Software / version / OS
vLLM OpenAI-compatible server, streaming; Python client on the same machine · vLLM 0.28.0; NVIDIA driver 580.178.04; CUDA 13.0 · DGX OS 7.6.0 (Ubuntu 24.04.5 LTS), kernel 7.0.0-1019-nvidia
Power profile
default DGX OS power settings, no manual limit; GPU power logged with nvidia-smi in the Our test section
Test conditions
nvidia/Qwen3.6-35B-A3B-NVFP4 (35B parameters, about 3B active, 4-bit NVFP4 weights); context window 131,072 tokens; thinking disabled; no speculative decoding; temperature 0.3; batch 1 (one request); 33-token prompt; 301, 305, 301 tokens generated in three runs (77.94, 77.95, 77.95 tokens/s, median shown); median time to first token 0.07 s (0.16 s on the cold first run)

Our own measurement on one unit. Other units, firmware or software versions can give different results.

73.97 tok/sMiniPC.guru test
Our test of the ASUS Ascent GX10 ↑

By MiniPC.guru · MiniPC.guru

Source published
Sep 25, 2026
Test performed
Sep 25, 2026
Added to MiniPC.guru
Sep 25, 2026
Source reviewed
Sep 25, 2026
Tested hardware
NVIDIA GB10, 20 Arm cores (10 × Cortex-X925 + 10 × Cortex-A725) · NVIDIA GB10 integrated Blackwell GPU · 128 GB LPDDR5X unified memory, 121.6 GiB visible to Linux · not applicable: the model is fully resident in memory
Software / version / OS
vLLM OpenAI-compatible server, streaming; Python client on the same machine · vLLM 0.28.0; NVIDIA driver 580.178.04; CUDA 13.0 · DGX OS 7.6.0 (Ubuntu 24.04.5 LTS), kernel 7.0.0-1019-nvidia
Power profile
default DGX OS power settings, no manual limit; GPU power logged with nvidia-smi in the Our test section
Test conditions
nvidia/Qwen3.6-35B-A3B-NVFP4 (35B parameters, about 3B active, 4-bit NVFP4 weights); context window 131,072 tokens; thinking disabled; no speculative decoding; temperature 0.3; batch 1 (one request); 8,620-token prompt (Moby-Dick excerpt with a hidden note, found: yes); 66 tokens generated; time to first token 1.74 s

Our own measurement on one unit. Other units, firmware or software versions can give different results.

65.55 tok/sMiniPC.guru test
Our test of the ASUS Ascent GX10 ↑

By MiniPC.guru · MiniPC.guru

Source published
Sep 25, 2026
Test performed
Sep 25, 2026
Added to MiniPC.guru
Sep 25, 2026
Source reviewed
Sep 25, 2026
Tested hardware
NVIDIA GB10, 20 Arm cores (10 × Cortex-X925 + 10 × Cortex-A725) · NVIDIA GB10 integrated Blackwell GPU · 128 GB LPDDR5X unified memory, 121.6 GiB visible to Linux · not applicable: the model is fully resident in memory
Software / version / OS
vLLM OpenAI-compatible server, streaming; Python client on the same machine · vLLM 0.28.0; NVIDIA driver 580.178.04; CUDA 13.0 · DGX OS 7.6.0 (Ubuntu 24.04.5 LTS), kernel 7.0.0-1019-nvidia
Power profile
default DGX OS power settings, no manual limit; GPU power logged with nvidia-smi in the Our test section
Test conditions
nvidia/Qwen3.6-35B-A3B-NVFP4 (35B parameters, about 3B active, 4-bit NVFP4 weights); context window 131,072 tokens; thinking disabled; no speculative decoding; temperature 0.3; batch 1 (one request); 30,832-token prompt (Moby-Dick excerpt with a hidden note, found: yes); 77 tokens generated; time to first token 6.43 s

Our own measurement on one unit. Other units, firmware or software versions can give different results.

48.51 tok/sMiniPC.guru test
Our test of the ASUS Ascent GX10 ↑

By MiniPC.guru · MiniPC.guru

Source published
Sep 25, 2026
Test performed
Sep 25, 2026
Added to MiniPC.guru
Sep 25, 2026
Source reviewed
Sep 25, 2026
Tested hardware
NVIDIA GB10, 20 Arm cores (10 × Cortex-X925 + 10 × Cortex-A725) · NVIDIA GB10 integrated Blackwell GPU · 128 GB LPDDR5X unified memory, 121.6 GiB visible to Linux · not applicable: the model is fully resident in memory
Software / version / OS
vLLM OpenAI-compatible server, streaming; Python client on the same machine · vLLM 0.28.0; NVIDIA driver 580.178.04; CUDA 13.0 · DGX OS 7.6.0 (Ubuntu 24.04.5 LTS), kernel 7.0.0-1019-nvidia
Power profile
default DGX OS power settings, no manual limit; GPU power logged with nvidia-smi in the Our test section
Test conditions
nvidia/Qwen3.6-35B-A3B-NVFP4 (35B parameters, about 3B active, 4-bit NVFP4 weights); context window 131,072 tokens; thinking disabled; no speculative decoding; temperature 0.3; batch 1 (one request); 94,722-token prompt (Moby-Dick excerpt with a hidden note, found: yes); 90 tokens generated; time to first token 26.56 s

Our own measurement on one unit. Other units, firmware or software versions can give different results.

530.4 tok/sMiniPC.guru test
Our test of the ASUS Ascent GX10: 32 users at once, total ↑

By MiniPC.guru · MiniPC.guru

Source published
Sep 25, 2026
Test performed
Sep 25, 2026
Added to MiniPC.guru
Sep 25, 2026
Source reviewed
Sep 25, 2026
Tested hardware
NVIDIA GB10, 20 Arm cores (10 × Cortex-X925 + 10 × Cortex-A725) · NVIDIA GB10 integrated Blackwell GPU · 128 GB LPDDR5X unified memory, 121.6 GiB visible to Linux · not applicable: the model is fully resident in memory
Software / version / OS
vLLM OpenAI-compatible server, streaming; Python client on the same machine · vLLM 0.28.0; NVIDIA driver 580.178.04; CUDA 13.0 · DGX OS 7.6.0 (Ubuntu 24.04.5 LTS), kernel 7.0.0-1019-nvidia
Power profile
default DGX OS power settings, no manual limit; GPU power logged with nvidia-smi in the Our test section
Test conditions
nvidia/Qwen3.6-35B-A3B-NVFP4 (35B parameters, about 3B active, 4-bit NVFP4 weights); context window 131,072 tokens; thinking disabled; no speculative decoding; temperature 0.3; batch 32 (32 concurrent requests, total throughput of all of them); short prompts, exactly 256 tokens generated per request; per-request median 17.02 tokens/s, slowest 16.86; median time to first token 0.45 s

Our own measurement on one unit. Other units, firmware or software versions can give different results.

Price history

ASUS Ascent GX10 · 128 GB RAM · 1 TB SSD

Latest observed—
Recorded low—
Period change—

Loading checks…

New condition · US stores · USD · Selected configuration only. Chart prices exclude shipping and tax. Missing or failed checks leave gaps.

About this data9 references

Specs come from the sources below. Results marked MiniPC.guru test were measured by us on our own unit, and their raw data is in the “Our test” section of this page; everything else comes from the sources listed.

Notes

  • Measured wall power and acoustic measurements remain unverified. Our own test logged GPU power with nvidia-smi, not at the wall; its language model results are under Performance.
  • ConnectX-7 link throughput needs a measured network test; adapter rating and device input rating must not be conflated.

Sources

  1. ASUS Ascent GX10 — manufacturer specifications ↗
    • Manufacturer / specification source
    • Selected configuration
    • Ports & displays · Reviewed Sep 15, 2026
    • Ethernet, Wi-Fi & Bluetooth · Reviewed Sep 15, 2026
    • RAM & storage upgrades · Reviewed Sep 15, 2026
    • Power supply & power limits · Reviewed Sep 15, 2026
    • Dimensions & weight · Reviewed Sep 15, 2026
  2. ASUS Ascent GX10 launch specifications ↗
    • Power supply & power limits · Reviewed Sep 15, 2026
  3. Our test of the ASUS Ascent GX10 ↑
    • MiniPC.guru test (“Our test” section, with raw data) · Reviewed Sep 25, 2026
  4. ASUS Ascent GX10 review: a new NVIDIA GB10 solution ↗
    • Owner review source · Reviewed Sep 25, 2026
  5. ASUS Ascent GX10 review ↗
    • Owner review source · Reviewed Sep 25, 2026
  6. Share your latest Ascent GX10 idle power ↗
    • Owner review source · Reviewed Sep 25, 2026
  7. GB10 on the ASUS GX10: GPU maxing out at 60 W ↗
    • Owner review source · Reviewed Sep 25, 2026
  8. GX10 against a MacBook Pro: is this performing to specification? ↗
    • Owner review source · Reviewed Sep 25, 2026
  9. The MacBook won the speed test ↗
    • Owner review source · Reviewed Sep 25, 2026